


Converting PDF Documents to Plain Text TXT in C#
The extraction of plain text from PDF documents for further processing, analysis or full text search is a common task. This article explains how to extract plain text from PDF documents programmatically with .NET C# and TX Text Control.
Extracting plain text from PDF documents for further processing, analyzing or searching is a common task. Typically, a PDF document contains a collection of characters at specific locations, and a filter is required to import the text to be extracted.
With TX Text Control, all typical word processing formats such as DOC, DOCX, RTF and PDF can be loaded for plain text extraction. The following code shows how to create a simple console application that loads a PDF document and then extracts the plain text from it.
Preparing the Application
A .NET 6 console application is created for the purposes of this demo.
Prerequisites
The following tutorial requires a trial version of TX Text Control .NET Server.
-
In Visual Studio, create a new Console App using .NET 6.
-
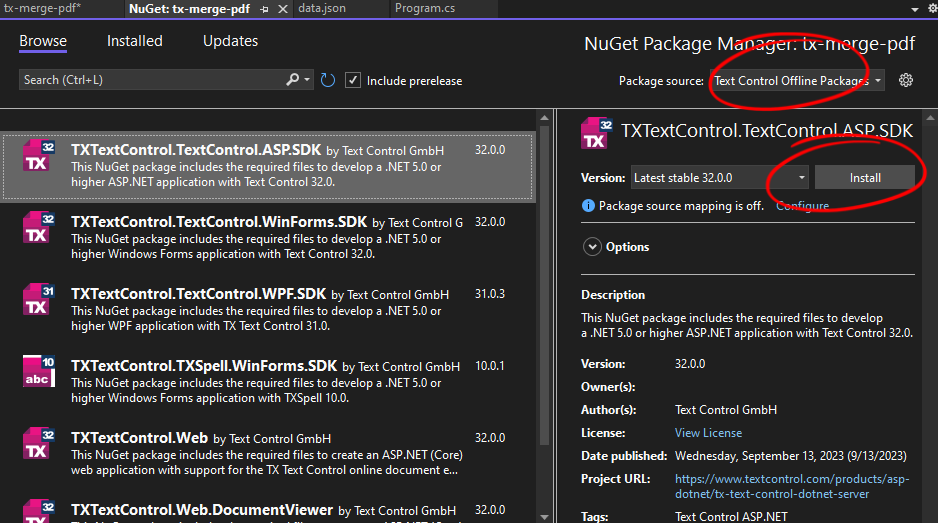
In the Solution Explorer, select your created project and choose Manage NuGet Packages... from the Project main menu.
Select Text Control Offline Packages from the Package source drop-down.
Install the latest versions of the following package:
- TXTextControl.TextControl.ASP.SDK
Adding a PDF
-
Create a folder named App_Data in the root of your project. Copy your PDF documents into this folder. In this example, the name of the PDF document that will be loaded is sample.pdf.
Adding the Code
-
Open the Program.cs file and add the following code:
using (TXTextControl.ServerTextControl tx = new TXTextControl.ServerTextControl())
{
    tx.Create();

    TXTextControl.LoadSettings ls = new TXTextControl.LoadSettings()
    {
        PDFImportSettings = TXTextControl.PDFImportSettings.GenerateParagraphs
    };

    // load PDF document
    tx.Load("App_Data/sample.pdf", TXTextControl.StreamType.AdobePDF, ls);

    // retrieve plain text
    var text = tx.Text;

    Console.WriteLine(text);
}
Alternatively, if the document is stored in a database or by some other method, you can load the document from a byte array.
byte[] document = File.ReadAllBytes("App_Data/sample.pdf");
tx.Load(document, TXTextControl.BinaryStreamType.AdobePDF, ls);
TX Text Control recognizes matching words to create paragraphs and returns plain text written to the console.
ASP.NET
Integrate document processing into your applications to create documents such as PDFs and MS Word documents, including client-side document editing, viewing, and electronic signatures.


- Angular
- Blazor
- React
- JavaScript
- ASP.NET MVC, ASP.NET Core, and WebForms
Related Posts
PDF Conversion in .NET: Convert DOCX, HTML and more with C#
PDF conversion in .NET is a standard requirement for generating invoices, templates, and accessible reports. This article provides an overview of PDF conversion capabilities using TX Text Control,…
ASP.NETASP.NET CoreDocument Conversion
Convert DOCX to PDF, PDF/A and PDF/UA in C# Using TX Text Control
Learn how to convert Word DOCX documents to PDF in C# using TX Text Control .NET Server. This tutorial covers file-based and in-memory conversion, PDF/A export, document metadata, font deployment,…
Reliable Document AI in .NET: LLM Tool Calling vs. LLM-Generated Files
Reliable document AI needs a deterministic engine. With LLM tool calling, the LLM decides what the document should contain, and TX Text Control generates the file.
ASP.NETASP.NET CoreDocument Generation
Building a Production-Ready PDF Generation Pipeline in C# with ASP.NET Core
Learn how to build a reliable PDF generation pipeline with TX Text Control and ASP.NET Core. Use durable background jobs, idempotency, renewable leases, PDF validation, and private artifact…
ASP.NETASP.NET CoreDocument Viewer
Native PDF Annotation Support Is Coming to the TX Text Control Document Viewer
The next version of the TX Text Control Document Viewer will introduce an important enhancement to PDF workflows: native support for PDF-compatible annotations. Users will be able to add…